Senior Data Engineer · Databricks · Speaker
Lucas Lessa
Data Engineer, Architect and Analyst with 5+ years of experience, specialized in Databricks, Azure and Power BI. I build scalable data platforms, Lakehouse architectures and high-performance pipelines, turning data into business value. I explore where Data Engineering meets Artificial Intelligence, building solutions with generative AI and multi-agent systems. I share knowledge and support the community through talks, YouTube and LinkedIn.
- Years of experience
- 5+
- Certifications
- 3
- Projects
- 5
- Talks
- 5
Tech Stack
Skills
Data engineering
Scalable Medallion pipelines, orchestrated with Jobs and Lakeflow.
SQL & PySpark
Tuning queries and pipelines over tens of millions of rows.
Analytics & BI
Dimensional modeling, Power BI and DAX for executive reporting.
Governance & AI
Data quality, versioning and AI applied to analytics.
Stack
Platforms
- Databricks
- Microsoft Azure
- Azure Data Factory
- Azure Synapse
- Power BI
Languages
- Python
- PySpark
- SQL
- DAX
Tools
- Delta Lake
- Lakeflow
- GitHub
- Azure DevOps
Quality & governance
- FinOps
- Unity Catalog
- Data Contracts
- Governed Tags
AI & Agents
- Genie Agents
- MCP
- Multi-agent systems
- Prompt Engineering
- Claude
Career
Experience
Data Engineer · Globalsys Soluções em TI
Data Engineer building and optimizing scalable solutions that support strategic decisions, focusing on architecture, performance, governance and data reliability.
- ▸Designed and rolled out complete production environments on Databricks, building a scalable data engineering platform from scratch with a focus on standardization, automation, governance and high availability.
- ▸Built scalable pipelines on Databricks (PySpark/SQL) and Azure Synapse Analytics using the Medallion Architecture (Bronze, Silver and Gold) to transform and serve analytical data.
- ▸Technical lead on strategic projects, mentoring junior engineers, spreading engineering best practices and contributing to architectural decisions.
- ▸Tuned queries and pipelines over more than 50 million records, cutting processing time and improving compute efficiency.
- ▸Integrated multiple data sources, including APIs, relational databases, SharePoint and Google Sheets, consolidating critical information for analytics.
- ▸Built and optimized analytical datasets and dimensional models for Power BI dashboards and executive reports.
- ▸Defined and implemented versioning, code review and code governance practices with GitHub and Azure DevOps, raising the standardization, quality and scalability of data engineering deliveries.
- ▸Orchestrated and monitored pipelines with Databricks Jobs and Lakeflow, ensuring automation and SLA compliance.
- ▸Trained business teams on analytics tools, fostering autonomy and a data-driven culture.
- ▸Spoke at tech events and communities, sharing knowledge about careers and data engineering.
- Databricks
- PySpark
- SQL
- Azure Synapse
- Power BI
- GitHub
- Azure DevOps
- APIs
- Data Quality
- Lakehouse Architecture
Consulting
Data Engineer · Dadoteca
Data engineering for a healthcare client, building and evolving a scalable Lakehouse platform on Databricks with Bronze, Silver and Gold layers, prioritizing performance, governance and trustworthy data for business decisions.
- ▸Built scalable pipelines on Databricks (PySpark/SQL) and Azure Synapse Analytics using the Medallion Architecture (Bronze, Silver and Gold) to transform and serve analytical data.
- ▸Integrated multiple data sources, including FHIR APIs and other healthcare interoperability standards, ingesting and processing JSON payloads.
- ▸Tuned queries and pipelines over more than 50 million records, cutting processing time and improving compute efficiency.
- ▸Orchestrated and optimized complex jobs in Azure Synapse Analytics, prioritizing performance, reliability and data traceability.
- ▸Versioning and data governance with Azure DevOps.
- ▸Prepared analytical data for Power BI, building consistent models, aggregations and dimensions to support decision-making.
- Databricks
- PySpark
- SQL
- Python
- Azure Synapse
- Azure DevOps
- Power BI
- APIs
- FHIR
- JSON
- Lakehouse
Consulting
Data Engineer · Exostack
Short-term strategic project for an agriculture client, focused on building the Bronze, Silver and Gold layers on Databricks.
- ▸Implemented the integration between Databricks and a production Progress (OpenEdge) database, ensuring secure connectivity and reliable ingestion.
- ▸Built ETL processes in Python.
- Databricks
- Progress OpenEdge
- Python
Mid-level Data Analyst · BeSmart
Data integration and modeling for reporting and decision-making, connecting multiple sources to Power BI.
- ▸Managed integrations with multiple data sources, including relational databases and CSV/Excel files.
- ▸Prepared and modeled analytical datasets for Power BI, building metrics, aggregations and reports to support decision-making.
- ▸Translated business requirements into data rules and transformations with SQL and Python in Pentaho Data Integration (PDI), ensuring standardized and reliable ETL processes.
- SQL
- Python
- Pentaho
- Power BI
Junior Data Analyst · Grupo Verzani & Sandrini
Database design, ETL processes and business KPIs.
- ▸Built and maintained databases.
- ▸Translated business requirements into data rules through ETL processes.
- ▸Built and maintained dashboards and KPIs in Power BI.
- SQL
- ETL
- Power BI
- Excel
Portfolio
Projects
Data engineering · Healthcare
FHIR API ingestion with Databricks
A data engineering pipeline integrating a healthcare API based on the HL7 FHIR standard into Databricks, using the Google Cloud Healthcare API as the data source and OAuth 2.0 for authentication.
The goal was to automate clinical data ingestion, turn FHIR resources into tabular structures and prepare them for queries, analytics and consumption by other layers of the data platform.
- Databricks
- PySpark
- HL7 FHIR
- OAuth 2.0
- Delta Lake
- Unity Catalog
- Google Cloud
Analytics & AI · Finance
Genie Agents - ROIC & P&L
A conversational agent built with Databricks Genie, focused on financial data and performance indicators, especially ROIC (Return on Invested Capital) and the P&L (income statement, DRE in Brazil).
The idea was to let users query financial information with natural-language questions, reducing reliance on hand-written SQL and on navigating traditional dashboards.
- Databricks Genie
- Unity Catalog
- SQL
- Parquet
- Prompt Engineering
Data platform · DevOps
Building a Databricks platform from scratch
Rolling out and structuring a Databricks data platform, separating development (DEV) and production (PRD) environments and building the infrastructure, governance and CI/CD processes needed to support the lifecycle of data solutions.
- Databricks
- Azure
- Unity Catalog
- Terraform
- Azure DevOps
- Microsoft Entra ID
- CI/CD
Data engineering · Finance
Financial comparison with Delta Lake Time Travel
A Databricks solution comparing the financial figures recorded at month-end close with the values loaded in the following days, tracking changes until the next close.
Using Delta Lake versioning, the solution retrieved historical snapshots and compared them with recent versions, revealing changes in financial values without duplicating the whole dataset.
- Databricks
- Delta Lake
- Time Travel
- PySpark
- SQL
- Databricks Jobs
Analytics & BI · Finance
Moving rolling calculations from Power BI to SQL
Refactoring and optimizing 3-, 6- and 12-month rolling calculations by moving complex DAX measures to the SQL layer. The solution covered the Actuals, Radar and Budget scenarios, kept the dynamic period selection in Power BI, simplified the measures and made business rules easier to maintain.
The report had a dynamic selector to switch between 3, 6 and 12 months, which led to many complex DAX measures with conditional calculations, filter-context manipulation and time logic, making maintenance harder and increasing the processing load in Power BI.
- Power BI
- DAX
- SQL
- Data Modeling
YouTube
Recent videos
Tutorials and technical content
The first videos are on the way
Tutorials on Databricks, data engineering and AI. Subscribe to get notified when the first one is out.
Publications
Blog
LinkedIn posts and articles I've written
LinkedIn
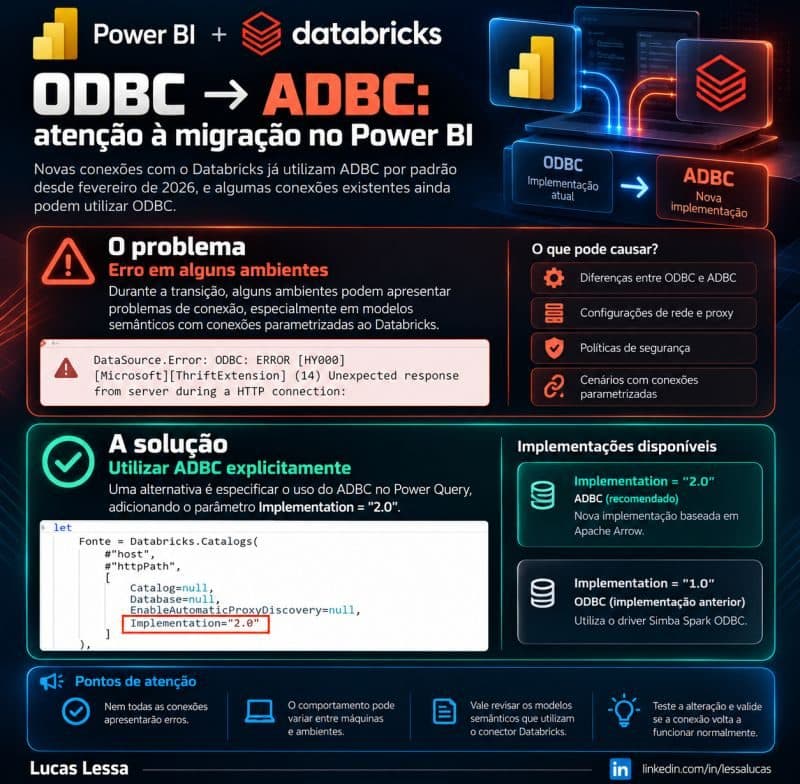
Power BI and Databricks: the ODBC-to-ADBC migration and the error it can cause
Power BI and Fabric connectors are switching from ODBC to ADBC. I show the error that hit parameterized models and the Implementation = 2.0 setting that fixed it.
Read on LinkedIn
LinkedIn
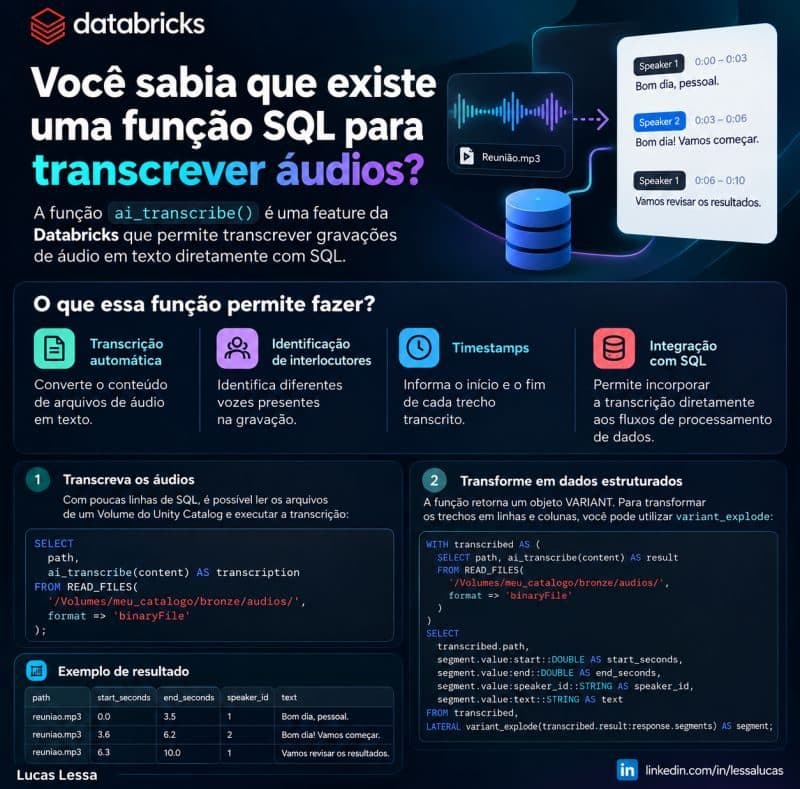
ai_transcribe: transcribing audio straight from SQL on Databricks
How to transcribe recordings stored in Unity Catalog Volumes, split speakers and timestamps with variant_explode, and the Beta limitations.
Read on LinkedIn
LinkedIn
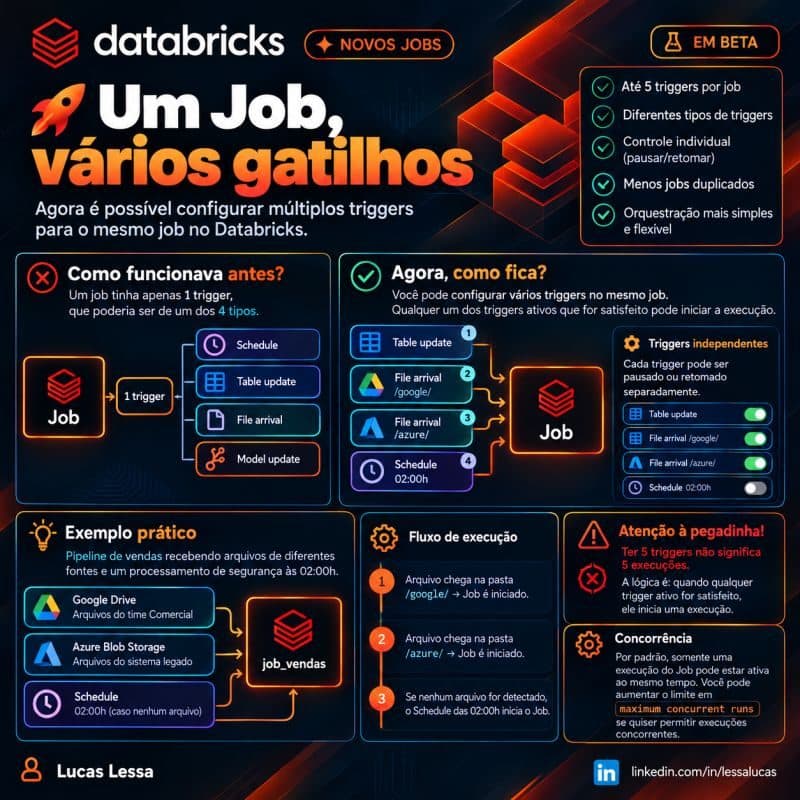
One job, many triggers: up to 5 triggers on the same Databricks job
A single job can now react to schedule, file arrival and table update at once. An example with a sales pipeline and the maximum concurrent runs gotcha.
Read on LinkedIn
LinkedIn
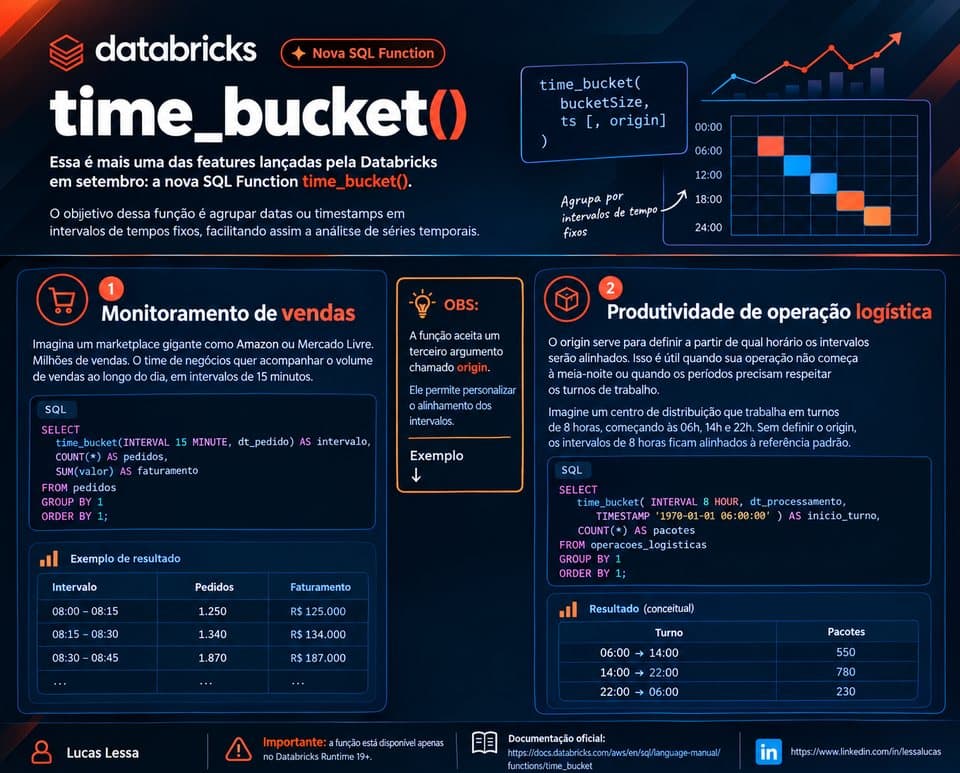
time_bucket(): grouping time series into fixed intervals in SQL
Databricks' new SQL function in practice: sales every 15 minutes and 8-hour logistics shifts using the origin argument. Available on Runtime 19+.
Read on LinkedIn
LinkedIn
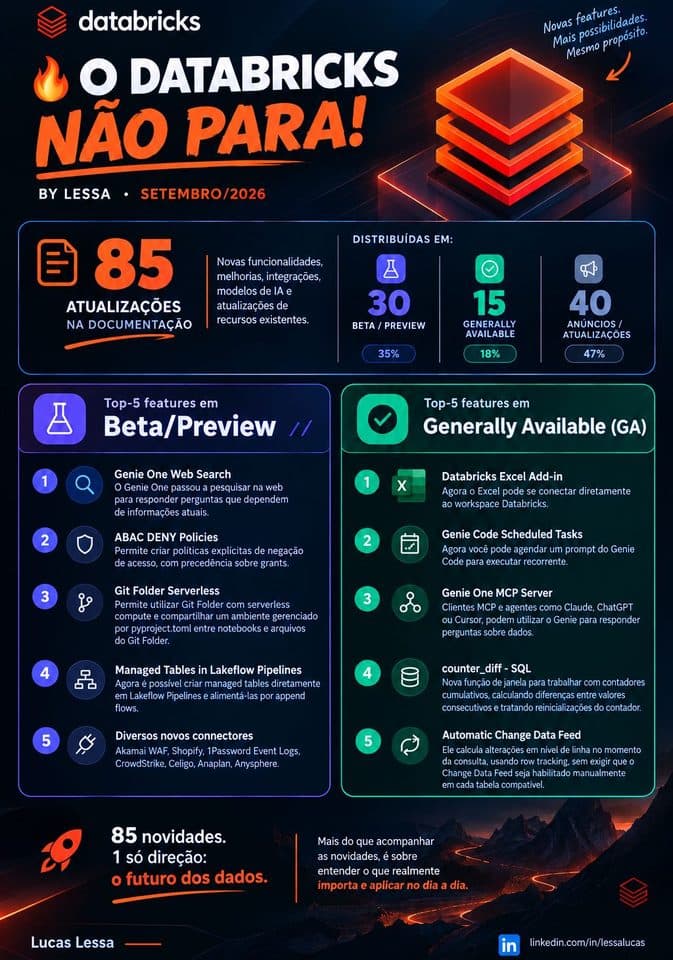
Databricks never stops: the September 2026 roundup
85 documentation entries in one month. The top 5 in Beta/Preview and top 5 in GA, from Genie One MCP Server to ABAC DENY Policies and Automatic Change Data Feed.
Read on LinkedIn
LinkedIn
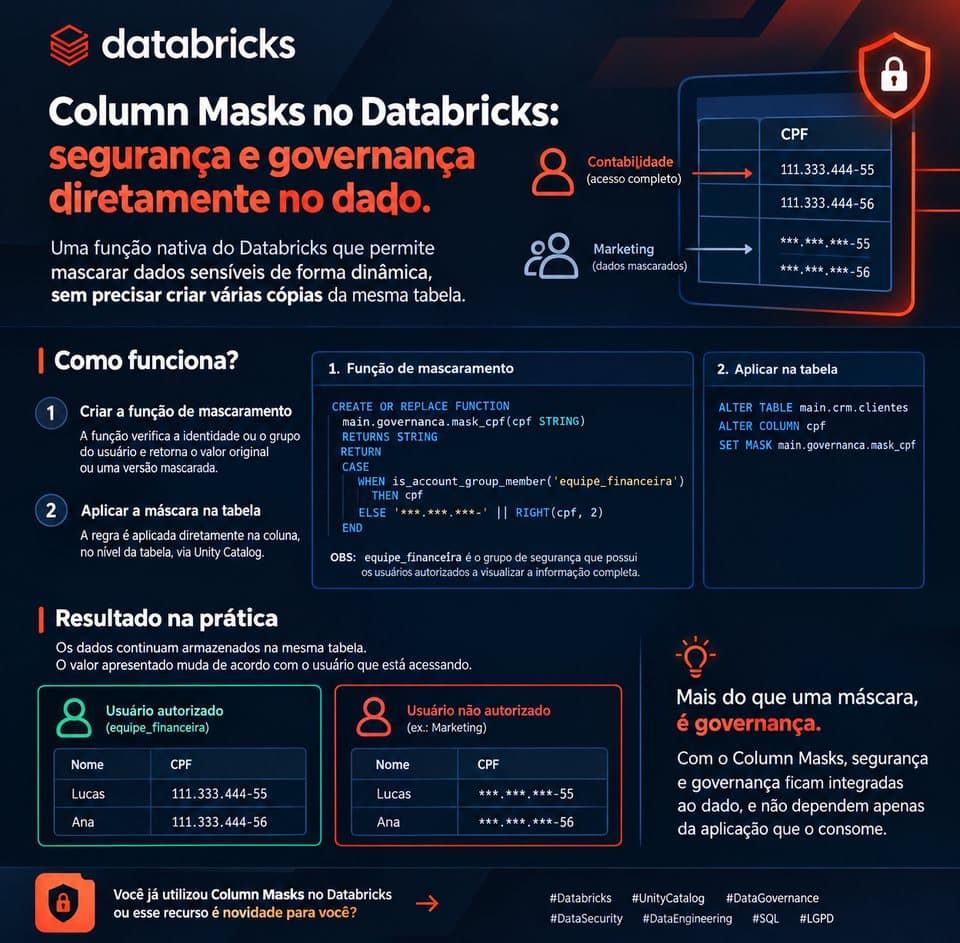
Column Masks: masking sensitive data without duplicating tables
Step by step to mask personal IDs by user group with a SQL function and ALTER TABLE ... SET MASK, serving finance and marketing from the same table.
Read on LinkedIn
LinkedIn
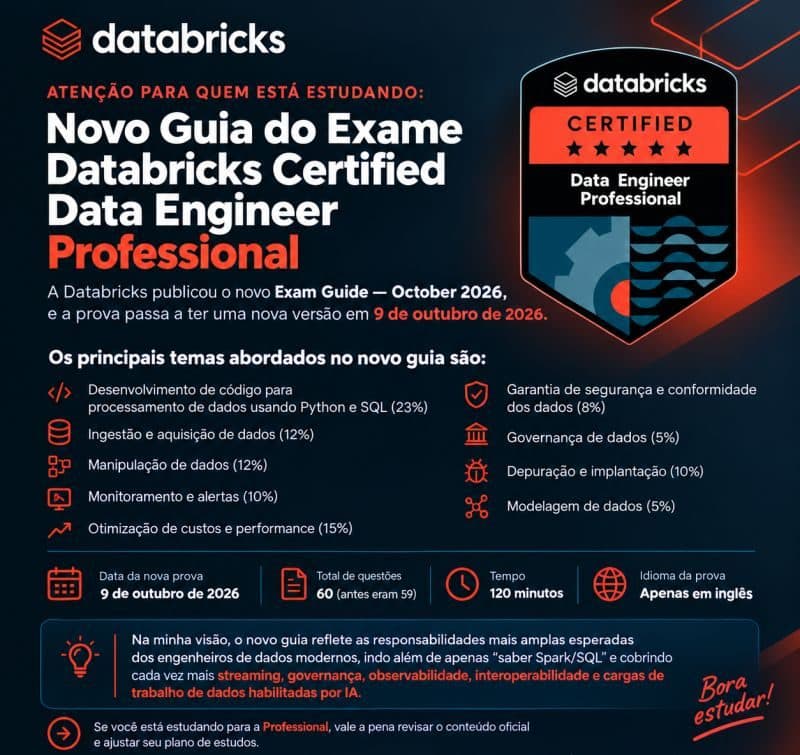
The Databricks Data Engineer Professional exam is changing
What changes in the new exam from October 9, 2026: highlighted topics, new sections and weights, English only, and what stays the same.
Read on LinkedIn
LinkedIn
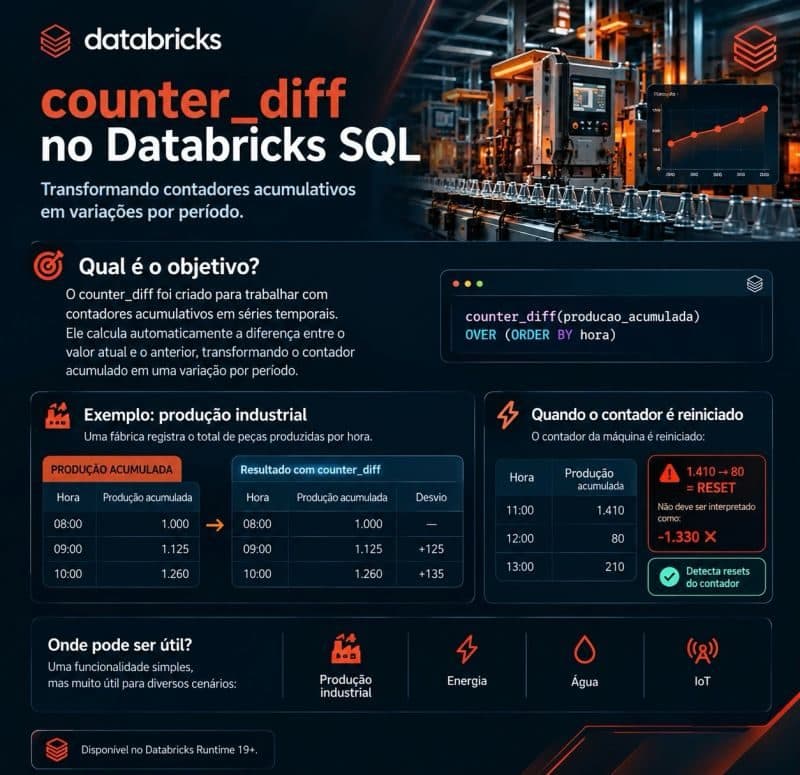
counter_diff: differences in cumulative counters, even across resets
Databricks SQL's new window function turns cumulative counters into per-period changes without mistaking a counter reset for a negative value. Runtime 19+.
Read on LinkedIn
LinkedIn
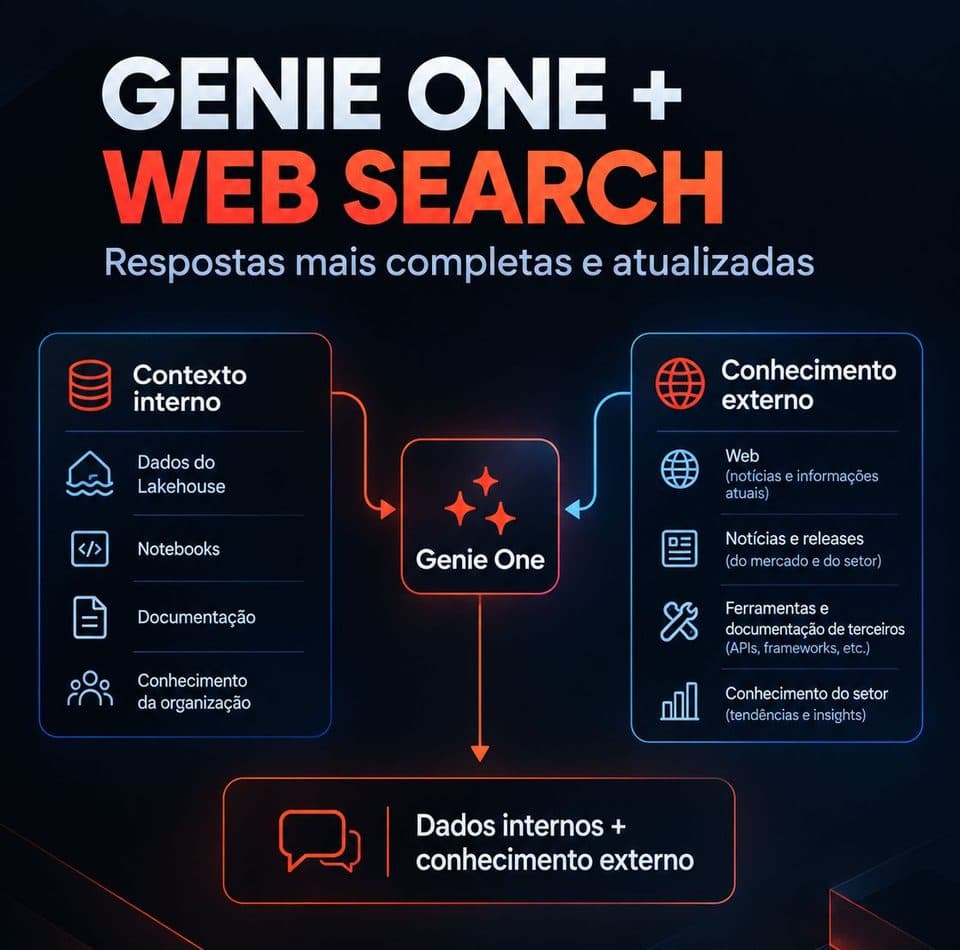
Genie One can now search the web
Genie One now searches the web for questions that need current information, always citing its sources. Usage examples and what it changes for analysis. In Beta.
Read on LinkedIn
LinkedIn
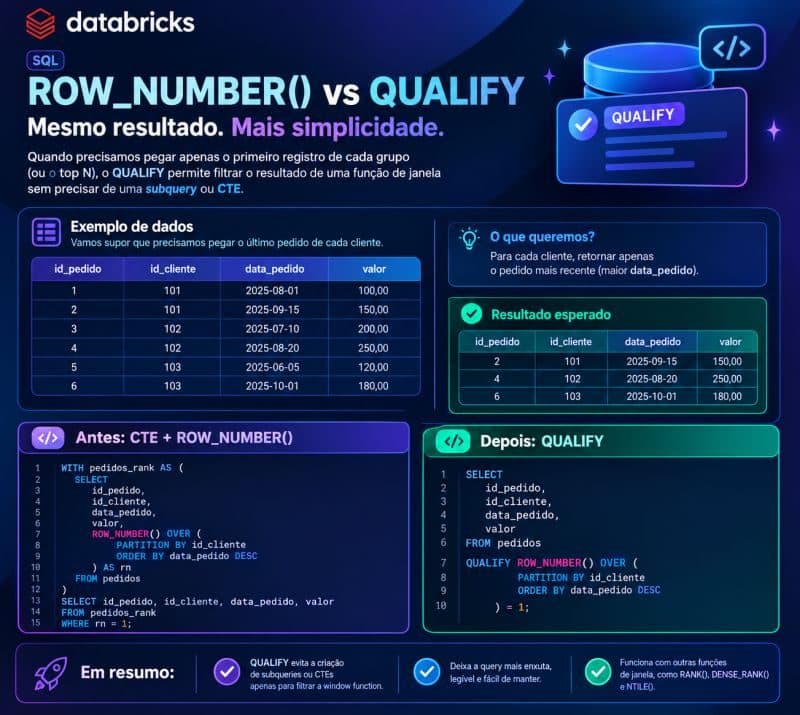
QUALIFY: filtering window functions without a CTE or subquery
From the classic CTE + ROW_NUMBER() to QUALIFY: the same result with far less code, including top 3 per customer with RANK().
Read on LinkedIn
LinkedIn
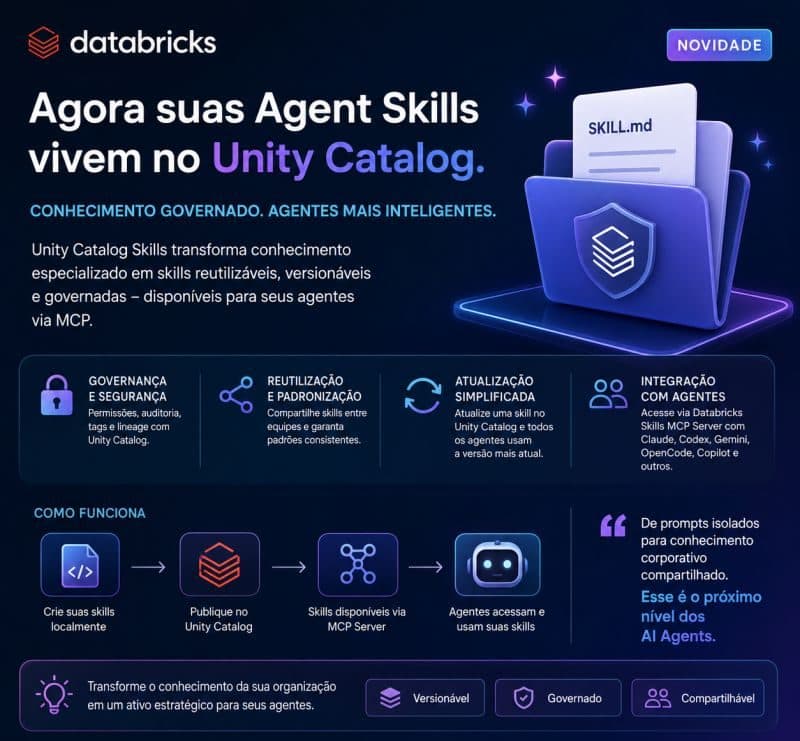
Skills in Unity Catalog: governed, reusable technical knowledge
Agent Skills are now Unity Catalog assets (catalog.schema.skill), with access control and auditing. Example: standardizing Silver-layer notebooks with Genie Code.
Read on LinkedIn
LinkedIn
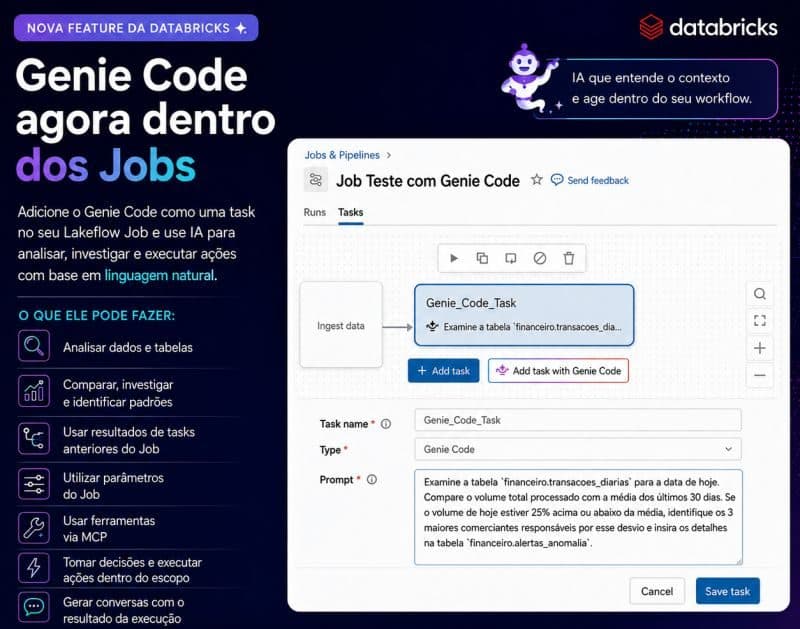
Genie Code task: AI inside your jobs
A task that takes a natural-language prompt, uses parameters and results from earlier tasks and acts in the workflow. Examples for transaction monitoring and data quality. In Beta.
Read on LinkedIn
Community
Talks
Events and communities where I shared knowledge
MVP Conf 2026
Databricks Genie - The end of the traditional dashboard era?
São Paulo, SP · Brazil
Are traditional dashboards coming to an end? In this talk I explore, without playing doomsday prophet, how agentic AI is changing the way we interact with data, the role of Databricks Genie in that shift, and the challenges behind it. After all, making data available isn't enough: it takes quality, governance, semantic context and reliable metrics for AI to give answers we can actually trust.
Data & AI Saturday #1156 Vitória
Claude Code + Databricks - The AI era
Vitória, ES · Brazil
How is the combination of Databricks and Claude Code changing the way we build data solutions? In this talk I explore the evolution of AI, the potential of agents and how tools like Skills, MCP and APIs make it possible to automate tasks, speed up development and build smarter solutions. All without losing sight of security, governance and the data engineer's role in the AI era.
SQL Saturday #1132 Belo Horizonte
Databricks Genie - The end of the traditional dashboard era?
Belo Horizonte, MG · Brazil
Are traditional dashboards coming to an end? In this talk I explore, without playing doomsday prophet, how agentic AI is changing the way we interact with data, the role of Databricks Genie in that shift, and the challenges behind it. After all, making data available isn't enough: it takes quality, governance, semantic context and reliable metrics for AI to give answers we can actually trust.
SQL Saturday
Databricks – How to become a Data Engineer?
Guarulhos, SP · Brazil
In this talk I share my path in Data Engineering, the main lessons from practice and the ways to get into the field or grow in it. I also show where Databricks fits in and which skills make the difference in building a solid data career.
SQL Saturday
Databricks – How to become a Data Engineer?
Vitória, ES · Brazil
In this talk I share my path in Data Engineering, the main lessons from practice and the ways to get into the field or grow in it. I also show where Databricks fits in and which skills make the difference in building a solid data career.
Background
Education
2026
In progressMBA in Data Science, Analytics and AI
USP/Esalq
2015 — 2019
Bachelor's in Production Engineering
Universidade Veiga de Almeida
2022
Data Science Bootcamp
IGTI
2021
Data Engineer Program
Data Science Academy
Certifications
Verify credentialDatabricks
Data Engineer Professional
Verify credentialDatabricks
Data Engineer Associate
Verify credentialMicrosoft · PL-300
Power BI Data Analyst Associate
A section of this site
Café com Features
Every Databricks, Snowflake and Microsoft Fabric update, explained in plain language and refreshed daily from the official release notes. Filter by platform.
Open Café com Features